Research essay · Agent architecture
When the Model Changes, What Happens to the Agent?
Model swaps, version upgrades, and the gap between the model we optimize for and the one we deploy.
An agent has been tuned for weeks. Its prompts are stable, its tools work, and its evaluation looks good. Then the production model changes: a cheaper provider, a new version of the same family, or a smaller model chosen to meet latency requirements. The API still accepts the request. The system no longer behaves the same way.
A search that once returned a concise answer becomes an exploratory loop. A model that used to wait for a tool result now emits several calls at once. A summarizer drops an unresolved constraint. A retry that helped the old model causes the new one to repeat a side effect. None of these requires a dramatic drop in general intelligence.
This is the problem I want to understand: what exactly have we optimized when we say that an agent system works? Is the improvement a reusable property of the system, a compensation for one model’s habits, or an interaction that disappears when either component changes?
An agent’s behavior belongs to the combination of model, harness, environment, and budget. Portability means preserving the task contract while measuring and limiting the work required to adapt that combination.
01 / The model is only one part of the deployed policy
I use harness for the model’s surrounding execution system: prompts, context assembly, memory, tool interfaces, routing, validators, retries, and stopping rules. A task outcome depends on all of these, together with the workload and available resources.
Even when code H stays fixed, replacing M changes the distribution of actions. Those actions change the environment and the observations fed into later decisions. A model swap therefore changes both the decision maker and the situations it will encounter.
Four changes deserve separate treatment.
| Change | Typical reason | What needs to be re-established |
|---|---|---|
| Same family, new version | Upgrade or provider retirement | Behavioral compatibility, including previously reliable edge cases |
| Different model or provider | Cost, latency, availability, capability | Interface semantics, task quality, operating budget |
| Tuned on A, deployed on B | Strong model used during development; cheaper executor in production | Whether the gains survive on B, and the adaptation cost |
| Model switch during a session | Routing, escalation, outage fallback | Whether B receives sufficient state and understands pending actions |
“A designed the workflow for B” is also different from “the workflow was evaluated and optimized on A, then copied to B.” A strong builder can propose useful code or examples for a weaker executor. The relevant selection signal is still B’s performance. The identity of the designer does not determine the target of optimization.
Historical work comparing March and June 2023 ChatGPT versions documented changes across tasks and instruction following.1 It supports behavioral regression testing. It does not let an external observer attribute a particular regression to a changed training-data mixture or reward function. For a black box, the actionable evidence is the observable contract and its failures.
02 / The dependencies hidden inside a “working” system
Some dependencies are obvious: a parser expects a field name, or a provider represents tool errors differently. Others are behavioral. The system assumes the model will search before answering, preserve an exception in a summary, recover after a failed edit, or stop once a task is complete.
A patch added during development can quietly turn one of these habits into a requirement. The old model ignores a constraint, so the prompt repeats it. The new model follows every repetition, checks the same condition several times, and runs out of time. A local repair has become a source of coupling.
| Dependency | What can change after a swap | Repair at the right layer |
|---|---|---|
| Output and tool protocol | Missing fields, different stop events, parallel calls | Normalize messages and validate schemas; preserve error semantics |
| Planning and stopping | More exploration, premature completion, excessive checking | Explicit completion evidence and bounded execution policies |
| Context and memory | Different use of summaries, tool outputs, or examples | Store facts and unresolved obligations with provenance; test reconstruction |
| Recovery | Repeating a failed action or treating a business rejection as an outage | Classify errors; define which actions can be retried safely |
| Budget | More reasoning, longer tool loops, higher tail latency | Measure quality against time and cost; tune operating points |
| Evaluation | A new answer style pleases the judge but violates the task | Independent end-state checks and audited judging examples |
The loop amplifies these differences. A slightly different first search changes the retrieved documents; that changes the plan, tool calls, accumulated context, and eventual stopping decision. Measuring only the first response misses the main effect.
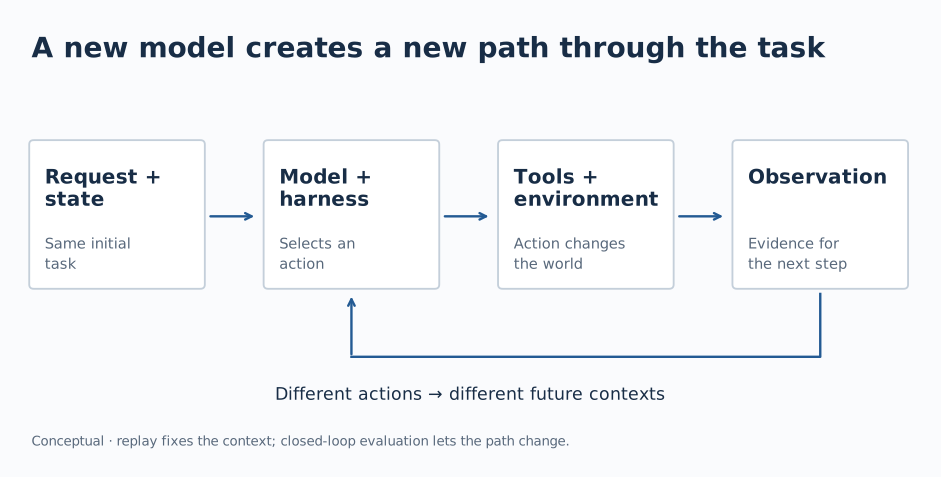
This explains why replay and live execution answer different questions. Feeding both models an identical recorded context is useful for locating a protocol or decision difference. It cannot reveal the states reached by B’s own earlier actions. Closed-loop runs are needed for end-to-end performance; controlled replay is useful for diagnosis.
03 / Portability is possible—and selective
The literature gives evidence in both directions. Sclar et al. found substantial sensitivity to meaning-preserving prompt formatting, with weak correlations in format performance between models.2 A shared prompt can therefore favor one model without being a neutral comparison.
SWE-agent provides a positive counterpart. Its agent-computer interface was developed around GPT-4 Turbo and also worked with Claude 3 Opus; on SWE-bench Lite, its interface improved resolution by 10.7 percentage points over a shell-only baseline.3 Useful interface structure can transfer even when the best wording or operating budget changes.
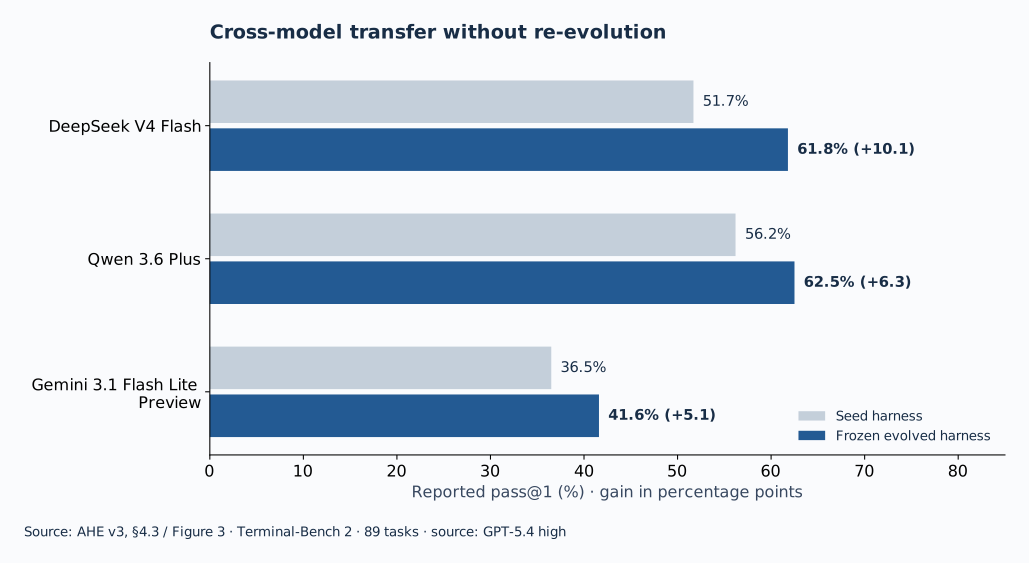
AHE’s cross-family gains range from 5.1 to 10.1 percentage points. Its component study also finds that transplanting the system prompt alone can regress. The report notes timeout-budget coupling: a configuration tuned for one reasoning level need not suit another.4
AI4AI at Test-Time studies a different setup: stronger builders construct harnesses for specified target models. In its theory-of-mind experiments, a stronger target regressed in 9 of 20 matched builder-by-benchmark comparisons, despite positive aggregate gains.5 These are target-specific constructions, not a direct test of copying an A-tuned harness to B. They expose the risk of adding structure where a target already performs well.
The useful distinction is between reusable task knowledge and model-specific compensation. An order must not be refunded twice: a durable requirement. “Ask the model to reconsider exactly three times”: a behavioral intervention whose benefit needs to be re-established.
04 / Separate the replacement effect from the adaptation opportunity
Suppose HA was tuned using model A and HB using model B. Evaluate both harnesses with both models on the same held-out workload. The off-diagonal cells are essential.
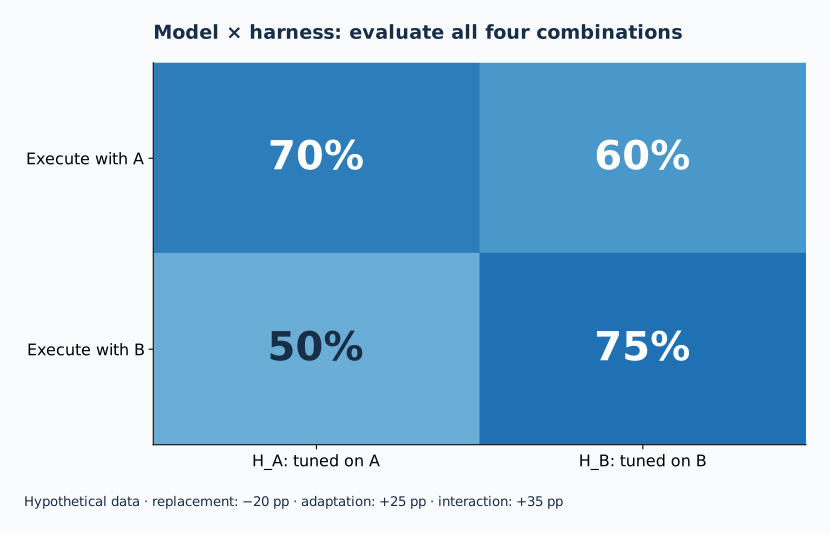
Adaptation = J(B,HB) − J(B,HA)
Interaction = [J(B,HB) − J(B,HA)] − [J(A,HB) − J(A,HA)]
In the illustrated matrix, the interaction is +35 percentage points. This tells us that the harness change helps B more than A under the tested conditions. It does not isolate a model’s context-free ability. HB is also merely the best configuration found under its search budget, not a known optimum.
The fixed-harness comparison answers the immediate deployment question: what happens if we replace the model today? The matched-adaptation comparison asks a different question: what could we obtain after giving each model a comparable tuning budget? Both are useful; reporting only one hides part of the decision.
Hold task instances, permissions, scorer, environment resets, and resource policies constant within each comparison. Report equal-dollar and equal-latency comparisons separately from equal-token or equal-turn comparisons. Tokens from different tokenizers, and turns containing different amounts of work, are not interchangeable resources.
This is more than bookkeeping. Anthropic reported a six-point Terminal-Bench 2.0 success difference between strict and uncapped resources while keeping the Claude model, harness, and tasks fixed.6 Infrastructure changes can look like a model effect.
05 / Decouple around contracts you can actually enforce
A single API wrapper solves transport compatibility. Behavioral portability needs a boundary between task requirements and model-specific means of satisfying them.
I would separate three layers: durable application state and requirements; an execution layer that mediates actions and records evidence; and a versioned model adapter for message rendering, tool representations, context packing, and operating settings.
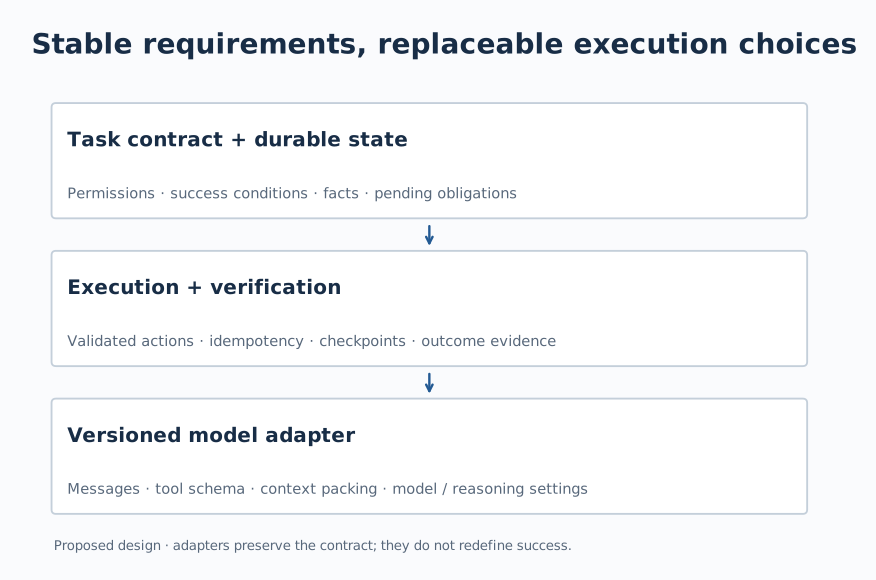
Consider a support agent that must refund an eligible order exactly once, record the result, and notify the customer only after confirmation. The model may propose the action. The tool layer checks eligibility against authoritative state, uses an idempotency key, and records the transaction identifier. After a timeout, the controller queries the transaction before retrying. Completion depends on the persisted result, not the model saying “done.”
These checks remove specific failure paths if correctly implemented. They do not determine whether the model understood an ambiguous request, selected the right evidence, or produced a useful explanation. Deterministic code can enforce a formalized boundary; semantic judgment remains a measured component of the system.
| Keep stable | Allow model-specific adaptation | Check at the boundary |
|---|---|---|
| Business predicates and permissions | Wording, examples, tool descriptions | Equivalent permitted actions and success conditions |
| Authoritative facts and event history | Context windows, summaries, retrieval order | Provenance, unresolved obligations, reconstruction accuracy |
| Side-effect semantics | Serial or parallel scheduling where dependencies permit | Idempotency, ordering, committed-state confirmation |
| Required delivery quality | Reasoning effort, retry and escalation thresholds | Held-out quality, tail latency, total cost |
| Evaluation contract | Model invocation and protocol conversion | No leakage of answers; stable grading criteria |
A schema catches a missing refund identifier; it cannot prove that a valid-looking identifier names the intended order. A summarizer can emit a valid object while omitting a crucial exception. Protocol validation must therefore connect to business predicates and evidence, rather than ending at successful parsing.
Anthropic’s Managed Agents separates the model-and-harness “brain,” execution tools, and a durable session event log.7 That is a useful example of lifecycle decoupling: a harness can restart from external state. It does not by itself establish cross-model behavioral equivalence.
Mid-session migration needs the same discipline. Hand over the goal, authoritative facts, completed and pending actions, unresolved obligations, and supporting evidence. Treat free-form summaries as derived views. Two models seeing the same prose is weaker than both reconstructing the same actionable state.
06 / Optimize for the executor you will actually deploy
DSPy separates declarative program structure from prompts and demonstrations optimized against a metric.8 MIPRO jointly searches instructions and examples for multi-stage programs.9 These offer a useful pattern: preserve the program’s intended transformation, then optimize how a target model carries it out.
For an A-to-B migration, keep a neutral baseline, the frozen A-tuned system, and a B-adapted system. Give the adapted baseline a recorded development budget. Otherwise, an elaborate migration method may appear useful only because its competitor received no tuning.
A strong builder can generate candidate demonstrations, tool descriptions, or modules. Select them using B on development tasks, check them on unseen task families, and account for the builder’s cost. If you select every candidate using A, then run only the winner on B, you have tested transfer after source optimization; you have not optimized B.
There is also a capability floor. An adapter cannot conjure missing visual input, unavailable tool permissions, or reliable long-context reasoning by renaming fields. A target may need a smaller task, retrieval, additional verification, or escalation. If these changes still cannot meet the contract at an acceptable cost, reject that model for that workload.
At the other end, a stronger model may need less scaffolding. Test removal as well as addition: fewer repeated reminders, fewer forced planning stages, or a simpler recovery loop. Agentless’s localization–repair–validation pipeline is a useful baseline for asking how much autonomous orchestration a task actually needs.10
07 / The cheapest model is not necessarily the cheapest system
A cheaper call can trigger more calls, more validation, more escalations, and more human repair. Evaluate cost per valid completion alongside total spend and unmet demand; a low cost among the few successful tasks can conceal widespread failure.
For a simple illustration, let the strong route cost 8 normalized units per request. A cheap route costs 1, verification costs 0.2, and a fraction f of requests falls back to the strong route, which costs another 8. These are illustrative costs, not provider prices.
| Fallback fraction f | Expected hybrid cost | Share of the direct strong-route cost |
|---|---|---|
| 10% | 2.0 | 25% |
| 50% | 5.2 | 65% |
| 85% | 8.0 | 100% |
| 100% | 9.2 | 115% |
This break-even calculation is useful only with a quality constraint. A verifier that misses bad outputs reduces observed fallback cost while degrading delivery. Measure false acceptance, unnecessary escalation, and the latency of the sequential fallback path. Also confirm that the fallback receives usable state rather than inheriting corrupted assumptions.
For a one-time adaptation cost K and validated recurring savings Δc per request, K/Δc is a simple amortization point when Δc is positive and workload conditions remain comparable. A model that retires before that volume is reached can erase the expected saving. Version lifetime is part of the economics of portability.
08 / Migrate a versioned system, not just a model name
A release should bind the model identifier, prompt and adapter versions, tool schemas, memory format, resource limits, routing policy, and grader version. Record provider revision identifiers where available. Pinning reduces ambiguity; it does not freeze external services or guarantee that the provider will keep a snapshot forever.
I would evaluate migration in layers, moving from cheap diagnostic tests to representative closed-loop execution.
| Stage | Main question | Evidence to retain |
|---|---|---|
| Interface checks | Can the system exchange valid requests, calls, results, and errors? | Parsing failures, unsupported semantics, lost fields |
| Controlled replay | Where do local decisions first diverge? | Identical contexts, action validity, matched perturbations |
| Closed-loop paired runs | Does the replacement complete the same work? | Reset tasks, repeated trials, outcome transitions, side effects |
| Held-out adaptation test | Did tuning repair the regression beyond development examples? | Task-family separation, frozen configurations, tuning cost |
| Shadow and limited rollout | Do offline results survive real traffic? | Representative slices, latency tails, escalation, external-state checks |
| Rollback rehearsal | Can the previous system resume safely? | Compatible state, versioned memories, reconciliation of committed actions |
An unchanged mean can hide different failures. If the old system succeeds on 80 of 100 tasks, and the new one fixes ten old failures but breaks ten old successes, both score 80%. The identities and costs of those regressions may determine whether the migration is acceptable. Repeat trials and report uncertainty rather than treating one stochastic pass/fail transition as a stable property.
τ-bench makes repeated-run reliability explicit through pass^k, the probability of consistent success across k trials.11 For migration, use both task-level transition analysis and reliability measures; distinguish model errors from infrastructure failures and missing evidence.
Shadow execution must isolate writes: running two refund agents against the same live order is not an independent comparison. Likewise, rolling back the model does not reverse an already issued refund or sent message. State reconciliation and compensating actions belong in the migration plan.
The acceptance rule should be chosen before reading target results: tolerated loss on each required workload slice, a bound on unacceptable actions, and cost or latency limits. Tail behavior and critical regressions should not disappear inside an average gain.
09 / What would make this a substantive research contribution?
The interesting object is the dependency that remains after API compatibility is solved. How much of a harness improvement transfers? Which components require retuning? How many target-model observations are needed to recover a specified quality level? Can we predict the failure before a full migration?
| Research question | Experiment | A result that would weaken the claim |
|---|---|---|
| Which dependencies are portable? | Cross model families with component swaps: prompts, tools, memory, recovery | Gains depend mainly on one source family or disappear under matched budgets |
| Can compatibility probes predict closed-loop regressions? | Freeze probes, then test unseen model versions and task families | Probe success does not improve prediction beyond a small random end-to-end sample |
| Does explicit state reduce mid-session migration failures? | Switch at matched checkpoints; compare transcript, summary, and structured-state handoffs with matched information | Benefits vanish when information content or handoff cost is controlled |
| Can adaptation be made cheaper? | Compare quality-versus-target-evaluation-cost curves against simple retuning | Similar quality requires comparable or greater total cost |
| Does a universal harness beat a small adapter family? | Compare a shared harness, lightweight adapters, and separately tuned systems | Separate tuning retains a large quality advantage with manageable maintenance |
These questions connect architecture to measurable outcomes. The objective need not be a single harness that wins everywhere. A practical result could be a stable task layer plus a small, well-tested set of adapters, with lower adaptation cost and fewer critical regressions than either direct replacement or full redevelopment.
The deepest shift is to treat model compatibility as a maintained empirical property. We already version code and schemas. An agent also needs evidence that a particular model, context policy, tool interface, and budget jointly satisfy its task contract.
A good architecture makes model changes easier to diagnose, cheaper to adapt to, and safer to reverse. Whether it achieves those benefits should be tested as directly as the agent’s task success.
Sources and figure data
Revised October 8, 2026. Figure 2 redraws reported data; Figures 1 and 4 are conceptual, and Figure 3 and the cost table are illustrative calculations. Data and sources.
- Chen, Zaharia, and Zou. How is ChatGPT’s behavior changing over time?. 2023 preprint; historical version comparison.
- Sclar et al. Quantifying Language Models’ Sensitivity to Spurious Features in Prompt Design. ICLR 2024.
- Yang et al. SWE-agent: Agent-Computer Interfaces Enable Automated Software Engineering. NeurIPS 2024; v3, interface analysis.
- Lin et al. Agentic Harness Engineering: Observability-Driven Automatic Evolution of Coding-Agent Harnesses. 2026 preprint, v3; Section 4.3 and Figure 3.
- Qian et al. AI4AI at Test-Time: Strong-to-Weak Capability Transfer via Harnesses. 2026 preprint, v1; Section 5.6.
- Anthropic. Quantifying infrastructure noise in agentic coding evals. Engineering report, February 2026.
- Anthropic. Scaling Managed Agents: Decoupling the brain from the hands. Engineering report, April 2026.
- Khattab et al. DSPy: Compiling Declarative Language Model Calls into Self-Improving Pipelines. ICLR 2024.
- Opsahl-Ong et al. Optimizing Instructions and Demonstrations for Multi-Stage Language Model Programs. EMNLP 2024; MIPRO.
- Xia et al. Agentless: Demystifying LLM-based Software Engineering Agents. 2024 manuscript, v2; three-stage baseline.
- Yao et al. τ-bench: A Benchmark for Tool-Agent-User Interaction in Real-World Domains. 2024 benchmark paper; repeated-run reliability.
Research essay · Agent architecture
模型换了,Agent 为什么变了?
模型替换、版本升级,以及“围绕一个模型优化,却用另一个模型生产”的迁移问题。
一个 Agent 已经调了几周。提示稳定了,工具能用了,评测结果也不错。接着,生产模型换了:换成便宜的服务商,同系列的新版本,或者为了延迟要求而选的小模型。API 仍能接受请求,系统的行为却变了。
原来能简洁完成的检索变成反复探索;原来等待工具结果的模型开始一次发出多个调用;摘要器漏掉尚未解决的约束;原本有帮助的重试,让新模型重复执行了有副作用的操作。这些变化都不需要以通用智能大幅下降为前提。
我真正想研究的是:当我们说一个 Agent 系统已经调好了,究竟调好了什么? 收益来自系统可复用的能力,来自对某个模型习惯的补偿,还是来自一旦更换组件就消失的相互配合?
Agent 的行为属于模型、外围系统、环境和预算的组合。可迁移性意味着保留任务要求,同时测量并限制适配这个组合所需的工作。
01 / 生产中的行为策略,不只由模型决定
本文用 harness 指模型外围的执行系统:提示、上下文组装、记忆、工具接口、路由、验证器、重试与停止规则。任务结果取决于这些部分,也取决于工作负载和可用资源。
即使代码 H 不变,更换 M 也会改变动作分布。动作改变环境,又改变后续决策读到的观察。因此,换模型同时改变了决策者,以及它接下来会遇到的情境。
至少应区分四类变化。
| 变化 | 常见原因 | 需要重新建立的依据 |
|---|---|---|
| 同系列换新版本 | 升级或旧版本退役 | 行为兼容,包括原本稳定的边界情况 |
| 更换模型或服务商 | 成本、延迟、可用性、能力 | 接口语义、任务质量与运行预算 |
| 在 A 上调优,在 B 上生产 | 开发用强模型,执行用便宜模型 | 收益能否在 B 上保留,以及适配成本 |
| 会话中途换模型 | 路由、升级处理、故障回退 | B 是否拿到足够状态,是否理解未完成动作 |
“A 为 B 设计工作流”,还不同于“工作流在 A 上评估和优化,再直接复制给 B”。强模型可以为弱执行器提出有用的代码或示例,但选择方案时,相关信号仍然应来自 B 的表现。设计者是谁,并不决定优化对象是谁。
比较 2023 年 3 月与 6 月 ChatGPT 版本的历史研究,记录了多类任务与指令遵循的变化。1 这支持开展行为回归测试,但外部观察者无法据此把某次退化归因于训练数据比例或奖励函数变化。面对黑箱,可操作的依据是可观察的行为要求,以及它在哪里失效。
02 / 一个“能用”的系统,藏着哪些依赖?
有些依赖很明显:解析器预期一个字段名,或者不同服务商表示工具错误的方式不同。另一些依赖属于行为:系统默认模型会先检索再回答,在摘要中保留例外条件,编辑失败后自行恢复,或者完成任务后及时停止。
开发中的一次修补,可能悄悄把某种习惯变成要求。旧模型忽略约束,于是提示反复强调;新模型认真执行每次强调,重复检查同一条件,最终超时。局部修复就这样变成了耦合来源。
| 依赖 | 换模型后可能出现的变化 | 应在哪一层修复 |
|---|---|---|
| 输出与工具协议 | 字段缺失、停止事件不同、并行调用 | 规范消息、校验 schema,同时保留错误语义 |
| 规划与停止 | 探索更多、提前结束、过度检查 | 明确完成证据,限制执行策略的范围 |
| 上下文与记忆 | 对摘要、工具结果、示例的使用方式变化 | 保存有来源的事实与未完成义务,检验状态重建 |
| 恢复 | 重复失败动作,把业务拒绝当成服务故障 | 区分错误类型,规定哪些操作可安全重试 |
| 预算 | 推理更多、工具循环更长、尾延迟更高 | 联合衡量质量、时间和成本,适配运行档位 |
| 评测 | 新回答风格更讨评分器喜欢,却违反任务要求 | 独立终态检查,审计评分示例 |
闭环会放大这些差异。第一次检索稍有不同,返回材料就不同;随后计划、工具调用、累积上下文与停止决策都会改变。只检查第一次回答,会漏掉主要影响。
这解释了回放和真实执行为什么回答不同问题。给两个模型输入相同的已记录上下文,有助于定位协议或局部决策差异,却看不到 B 因自身先前动作而进入的状态。端到端表现需要闭环运行,受控回放则适合诊断。
03 / 迁移可以成功,但不同部分并不一样
文献提供了两个方向的证据。Sclar 等人发现,保持含义的提示格式变化也会显著影响表现,而且格式优劣在模型之间只有较弱相关性。2 因此,共用一个提示可能偏向某个模型,并不天然构成中性的比较。
SWE-agent 提供了正向例子。它围绕 GPT-4 Turbo 开发的 Agent—计算机接口,也能用于 Claude 3 Opus;在 SWE-bench Lite 上,该接口比只使用 shell 的基线提高了 10.7 个百分点的解决率。3 有用的接口结构可以迁移,即使最佳措辞与运行预算发生变化。
AHE 的跨家族收益为 5.1 至 10.1 个百分点。组件实验也发现,只移植系统提示可能退化。报告指出了超时预算耦合:为某个推理档位调好的配置,未必适合另一个档位。4
AI4AI at Test-Time 研究另一种设置:强构建者为指定目标模型设计 harness。在其心智理论实验中,更强目标模型虽然总体受益,却在 20 个配对的“构建者 × benchmark”比较中有 9 个退化。5 这是面向各目标构建的系统,不是直接把 A 上调好的 harness 复制给 B 的实验。它揭示了向原本已经做得好的目标继续添加结构的风险。
有用的区分是:可复用的任务知识,与对特定模型的补偿。“订单不能重复退款”是持久要求;“要求模型恰好反思三次”是一种行为干预,其收益需要重新验证。
04 / 分开比较直接替换的影响与重新适配的空间
设 HA 围绕模型 A 调优,HB 围绕模型 B 调优。在相同留出工作负载上,让两个模型分别运行两个 harness。矩阵中的交叉位置尤其重要。
Adaptation = J(B,HB) − J(B,HA)
Interaction = [J(B,HB) − J(B,HA)] − [J(A,HB) − J(A,HA)]
图中交互项为 +35 个百分点。它说明,在被测条件下,harness 的变化对 B 比对 A 更有帮助,却没有隔离出模型脱离上下文的能力。HB 也只是给定搜索预算下找到的配置,而不是已知最优解。
固定 harness 的比较回答直接的部署问题:今天只换模型,会发生什么?匹配适配预算的比较回答另一件事:给各模型相当的调优机会后,可以达到什么水平?两者都有价值,只报告一种会遮住部分决策信息。
每组比较中,应固定任务实例、权限、评分器、环境重置与资源规则。相同金额、相同延迟的比较,应与相同 token 或轮次的比较分别报告。不同分词器的 token,以及工作量不同的轮次,并不是可互换的资源。
这不只是记账。Anthropic 在保持 Claude 模型、harness 和任务不变的条件下,报告了严格资源限制与不设上限之间六个百分点的 Terminal-Bench 2.0 成功率差异。6 基础设施变化也可能看起来像模型效应。
05 / 围绕真正可执行的要求解耦
统一 API 包装解决的是调用兼容。行为可迁移性需要进一步区分:任务必须满足什么,以及特定模型用什么方式满足它。
我会分成三层:持久的业务状态与要求;管理动作并记录证据的执行层;以及负责消息呈现、工具表示、上下文组装和运行设置的版本化模型适配层。
例如,一个客服 Agent 需要对符合条件的订单恰好退款一次,记录结果,并在确认后通知客户。模型可以提出操作,工具层根据权威状态检查资格,使用幂等键,记录交易标识。发生超时后,控制器先查询交易,再决定是否重试。任务完成依据持久化结果,而非模型说“完成了”。
这些检查在正确实现时,可以消除特定失败路径,却不能决定模型是否理解了含糊请求、选对了证据、给出了有用解释。确定性代码能执行已经形式化的边界,语义判断仍是系统中需要测量的部分。
| 保持稳定 | 允许按模型适配 | 在边界检查 |
|---|---|---|
| 业务条件与权限 | 措辞、示例、工具描述 | 允许动作与成功条件等价 |
| 权威事实与事件历史 | 上下文窗口、摘要、检索顺序 | 来源、未完成义务、重建准确性 |
| 副作用语义 | 在依赖允许时串行或并行 | 幂等性、顺序、持久状态确认 |
| 必须达到的交付质量 | 推理档位、重试与升级阈值 | 留出质量、尾延迟、总成本 |
| 评测要求 | 模型调用与协议转换 | 答案不泄漏,评分标准稳定 |
schema 能发现退款标识缺失,却不能证明一个格式正确的标识指向了用户真正要处理的订单。摘要器也可能输出合法对象,同时漏掉关键例外。因此,协议验证要连接业务条件和证据,而不能止于成功解析。
Anthropic 的 Managed Agents 把“模型与 harness”、执行工具,以及持久会话事件日志分开。7 这是生命周期解耦的具体例子:harness 可以从外部状态恢复。它本身还没有建立跨模型的行为等价性。
会话中途换模型也需要这种设计。交接目标、权威事实、已完成与待处理动作、未满足要求,以及支持证据。自由文本摘要是这些状态的派生视图。两个模型读到同一段话,比两个模型都能重建同一份可执行状态,要弱得多。
06 / 围绕真正上线的执行器优化
DSPy 将声明式程序结构,与根据指标优化的提示和示例分开。8 MIPRO 联合搜索多阶段程序的指令与示例。9 它们提供了一个有用模式:保留程序想完成的转换,再优化目标模型怎样执行。
对于 A 到 B 的迁移,应保留简单基线、冻结的 A 调优系统,以及面向 B 适配的系统。给适配基线明确记录的开发预算。否则,复杂迁移方法看起来有用,可能只是因为对照方法没有获得调优机会。
强构建者可以生成候选示例、工具描述或模块;用 B 在开发任务上的结果选择方案,再检查未见任务家族,并计入构建者成本。如果全部候选都由 A 的成绩筛选,最后只把赢家拿给 B 跑,那检验的是源模型优化后的迁移,而不是对 B 的优化。
适配也存在能力下限。改字段名不能凭空补出视觉输入、缺失的工具权限或可靠的长上下文推理。目标模型可能需要更小的子任务、检索、额外验证或升级处理。如果这些改动仍无法在可接受成本下满足任务要求,就应拒绝把该模型用于这类工作。
另一端,更强模型可能需要更少的外围约束。除了添加,也要测试删除:减少重复提醒,减少强制规划阶段,简化恢复循环。Agentless 的“定位—修复—补丁验证”流程,是检验任务究竟需要多少自主编排的有用基线。10
07 / 最便宜的模型,未必形成最便宜的系统
便宜的一次调用,可能带来更多调用、验证、升级处理与人工修复。应把每次有效完成的成本,与总支出和未满足需求一起看;少数成功任务的低成本可能掩盖大面积失败。
举一个简单例子:强模型路径每次请求成本为 8 个归一化单位;便宜路径为 1,验证为 0.2,有比例 f 的请求回退到强路径,再花 8。这是示意成本,而非服务商价格。
| 回退比例 f | 混合路径期望成本 | 占直接强模型路径成本 |
|---|---|---|
| 10% | 2.0 | 25% |
| 50% | 5.2 | 65% |
| 85% | 8.0 | 100% |
| 100% | 9.2 | 115% |
这个收支平衡计算需要质量约束才有意义。验证器漏掉错误输出,会降低观测到的回退成本,却损害交付。要测误接收、不必要升级,以及串行回退路径的延迟;还要确认回退模型得到可用状态,而不是继承已被污染的假设。
若一次性适配成本为 K,经验证每次请求节省 Δc,在 Δc 为正且工作负载可比时,K/Δc 是简单的摊销点。如果模型在达到该使用量之前就退役,预期节省可能消失。版本生命周期也是可迁移性的经济条件。
08 / 迁移一个系统版本,而不只是改模型名
一个发布版本应绑定模型标识、提示与适配器版本、工具 schema、记忆格式、资源限制、路由规则和评分器版本。有提供方修订标识时,也应记录。固定版本能减少歧义,但不会冻结外部服务,也不保证提供方永久保留快照。
迁移评估可以分层,从便宜的诊断检查,推进到有代表性的闭环执行。
| 阶段 | 主要问题 | 保留的证据 |
|---|---|---|
| 接口检查 | 请求、调用、结果和错误能否有效交换? | 解析失败、不支持的语义、丢失字段 |
| 受控回放 | 局部决策从哪里开始分化? | 相同上下文、动作有效性、匹配扰动 |
| 闭环配对运行 | 替换后能否完成相同工作? | 重置任务、重复试验、结果转移、副作用 |
| 留出适配测试 | 调优能否修复开发样本之外的退化? | 任务家族隔离、冻结配置、调优成本 |
| 影子与有限流量发布 | 离线结果能否在真实流量成立? | 有代表性的分组、尾延迟、升级处理、外部状态检查 |
| 回滚演练 | 旧系统能否安全恢复? | 兼容状态、版本化记忆、已提交动作的核对 |
均值不变也可能掩盖不同失败。旧系统在 100 个任务中完成 80 个,新系统修复十个旧失败,又破坏十个旧成功,两者仍是 80%。哪些任务退化、代价多大,可能直接决定是否接受迁移。需要重复试验并报告不确定性,不能把一次随机成败转移当作稳定属性。
τ-bench 通过 pass^k 明确衡量重复运行的一致成功,即 k 次试验持续成功的概率。11 迁移评估应同时使用任务级转移分析与可靠性指标,并区分模型错误、基础设施失败和证据缺失。
影子运行必须隔离写入:两个退款 Agent 操作同一真实订单,不是独立比较。同样,回滚模型不会撤销已经发出的退款或消息。状态核对与补偿操作也属于迁移方案。
验收规则应在看到目标结果前确定:每个必要工作分组容忍多大损失,哪些动作不可接受,以及成本或延迟上限。尾部行为和关键退化不应消失在平均收益里。
09 / 怎样把它变成实质性的研究问题?
值得研究的对象,是 API 兼容解决后仍然存在的依赖:harness 收益能迁移多少?哪些组件必须重调?恢复指定质量需要多少目标模型观测?能否在完整迁移前预测失效?
| 研究问题 | 实验 | 会削弱主张的结果 |
|---|---|---|
| 哪些依赖可以迁移? | 交叉模型家族,分别替换提示、工具、记忆、恢复组件 | 收益主要依赖单一源家族,或在匹配预算后消失 |
| 兼容性探测能预测闭环退化吗? | 冻结探测规则,测试未见版本与任务家族 | 不比少量随机端到端样本更能预测退化 |
| 显式状态能减少会话中途迁移失败吗? | 在匹配检查点切换,比较完整轨迹、摘要、结构化状态;匹配信息 | 控制信息量或交接成本后收益消失 |
| 能否降低适配成本? | 比较质量随目标模型评测成本变化的曲线,对照简单重调 | 达到相似质量需要相当或更高总成本 |
| 通用 harness 是否优于小型适配器族? | 比较共享 harness、轻量适配器、各自独立调优系统 | 独立调优保持明显质量优势,且维护成本可接受 |
这些问题把架构选择连接到可测量的结果。目标未必是一个在所有地方都获胜的通用 harness。一个有价值的结果,可以是稳定任务层加一组经过验证的小型适配器,使适配成本和关键退化都少于直接替换或全面重建。
更深的变化,是把模型兼容性当作需要持续维护的经验事实。我们已经为代码和 schema 做版本管理;Agent 还需要证据,说明某个模型、上下文策略、工具接口和预算的组合,确实满足任务要求。
好的架构应让换模型更容易诊断、更便宜地适配、更可靠地回退。这些收益应该像任务成功率一样,被直接检验。
资料与图表数据
2026 年 10 月 8 日修订。图 2 重绘公开数据;图 1、4 为概念图;图 3 与成本表为示意计算。 数据与来源.
- Chen, Zaharia, and Zou. How is ChatGPT’s behavior changing over time?. 2023 预印本;历史版本比较。
- Sclar et al. Quantifying Language Models’ Sensitivity to Spurious Features in Prompt Design. ICLR 2024。
- Yang et al. SWE-agent: Agent-Computer Interfaces Enable Automated Software Engineering. NeurIPS 2024;v3,接口分析。
- Lin et al. Agentic Harness Engineering: Observability-Driven Automatic Evolution of Coding-Agent Harnesses. 2026 预印本 v3;第 4.3 节与图 3。
- Qian et al. AI4AI at Test-Time: Strong-to-Weak Capability Transfer via Harnesses. 2026 预印本 v1;第 5.6 节。
- Anthropic. Quantifying infrastructure noise in agentic coding evals. 工程报告,2026 年 2 月。
- Anthropic. Scaling Managed Agents: Decoupling the brain from the hands. 工程报告,2026 年 4 月。
- Khattab et al. DSPy: Compiling Declarative Language Model Calls into Self-Improving Pipelines. ICLR 2024。
- Opsahl-Ong et al. Optimizing Instructions and Demonstrations for Multi-Stage Language Model Programs. EMNLP 2024;MIPRO。
- Xia et al. Agentless: Demystifying LLM-based Software Engineering Agents. 2024 稿件 v2;三阶段基线。
- Yao et al. τ-bench: A Benchmark for Tool-Agent-User Interaction in Real-World Domains. 2024 benchmark 论文;重复运行可靠性。